Bayesian media mix modelling
A media mix model estimates how much each channel contributes to sales while accounting for carryover and saturation. A Bayesian approach makes prior assumptions explicit and returns a range of plausible outcomes rather than a single point estimate.
8 min read · Updated September 7, 2026
What it is
A media mix model, or MMM, is a statistical model that explains a business outcome, usually revenue or orders, as the sum of a baseline and the contribution of each marketing channel over time. It works on aggregate data: weekly spend by channel, weekly sales, plus the things that also move sales, such as price, promotions, seasonality and competitors. It does not need user-level tracking, which is why it survived the end of third-party cookies.
The model is Bayesian when every parameter starts with a prior, a stated belief about its plausible range, and the data updates that belief into a posterior. The output is a distribution for each channel’s effect.
Why it matters for a media plan
Platform dashboards report what they can see. Attribution overlaps across channels, and a saturated channel keeps reporting a healthy average return long after the next euro stopped earning it. A media mix model looks at the same weeks from the outside and asks a different question: when spend on this channel went up, what happened to sales that the other channels and the calendar do not already explain?
That question is the one a budget decision needs. The model’s answer is a response curve per channel, and the curve is what turns “this channel has a 4× ROAS” into “the next €10,000 on this channel earns 0.9×, and on that one 3.1×”.
How it works
Every MMM decomposes the outcome into additive parts:
sales(t) = baseline
         + Σ over channels of  β × saturation( adstock( spend(t) ) )
         + seasonality(t) + trend(t) + controls(t) + noise
Three pieces do the work.
Adstock carries a week’s spend forward, because advertising keeps working after it runs. The usual form is geometric adstock: each week, a fixed share of last week’s effect remains.
Saturation bends the effect, because the second million does less than the first. The usual form is the Hill function: a curve with a half-saturation point and a shape.
The coefficient β scales the transformed spend into revenue. Its posterior, divided by spend, is the channel’s incremental return.
The Bayesian part is the priors. A well-built model uses three tiers of them. Structural parameters such as adstock decay get strong priors, because media physics is well known: search decays in days, television over weeks. Saturation gets moderate priors, tied to the channel’s typical spend. The channel coefficients get weak priors, so the data can speak, constrained to be positive. A useful default for the coefficients is to scale their prior by the channel’s share of the historical budget: the business’s own allocation encodes what it already believes.
Fitting is done by Markov chain Monte Carlo sampling. The result is a set of posterior draws for every parameter, and everything downstream, response curves, contributions, scenario projections, is computed on those draws. That is where the bands on a Kuwalyst plan come from.
How Kuwalyst uses it
The Media Planner runs data-backed plans on a Bayesian MMM fitted to the brand’s warehouse: weekly spend by channel, revenue, orders and the funnel, typically two to three years of it. The model card, the priors, the response curves and the fit diagnostics are stored as artefacts the team can inspect.
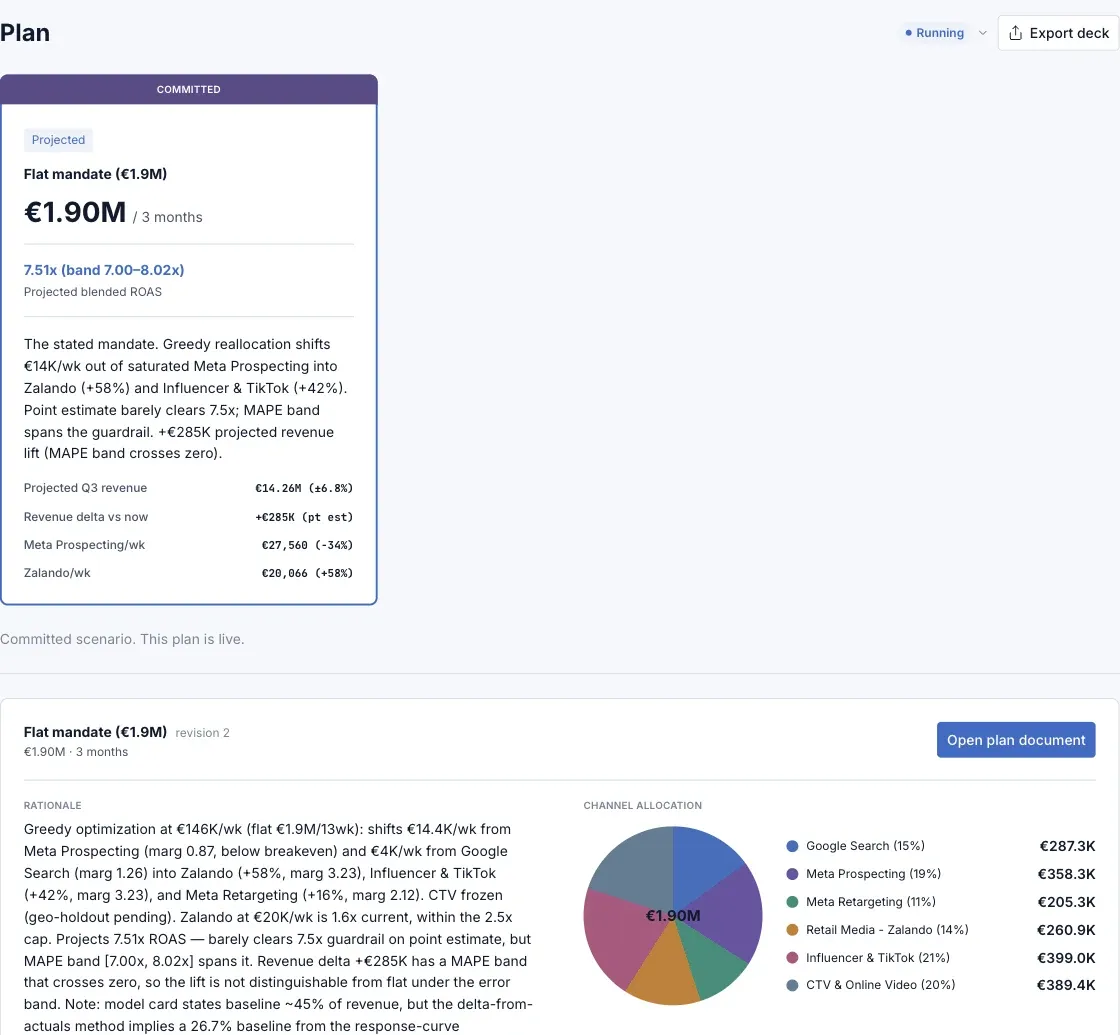
Allocation never uses average ROAS. It uses the marginal incremental ROAS read off each channel’s response curve at its current spend, so budget moves from channels that have saturated to channels with room. Scenario projections carry the posterior band, and the plan says when the band crosses zero: a projected lift that is not distinguishable from flat is reported as such.
When a channel’s band is too wide to decide on, the planner proposes the experiment that would narrow it, usually a geo-lift test. The measured result becomes a prior in the next fit. That loop, model, test, recalibrate, is the difference between a model that was built once and one that keeps earning its place.
Models your team or a partner already built can be loaded as artefacts too. The planner does not insist on its own.
Pitfalls
Good fit is not correct attribution: a model can predict sales well and still credit the wrong channel, because channels move together: everyone spends more in the fourth quarter. R² and out-of-sample error are necessary, not sufficient. The test of attribution is a lift test.
The branded search trap: television creates branded searches; an additive model credits the sale to search. Upper-funnel channels get under-credited and lower-funnel ones over-credited. The remedies range from reallocating with external evidence to modelling branded search as a mediator, and the plan should say which was used.
Flat priors, wild posteriors: with short data, uninformative priors produce implausible returns and sampling trouble. Priors that are too tight do the opposite: the posterior is the prior and the data never mattered. Prior sensitivity, refitting with priors moved by a reasonable amount, is the check.
No variation, no answer: a channel whose weekly spend has a coefficient of variation under 0.1 is not identifiable from the data. The model will return its prior. Say so, and test it instead.
Time-varying effects on short data: letting coefficients drift over time needs five years or more and a documented regime change. Otherwise fixed coefficients with honest bands are more reliable.
When not to use it
A media mix model is the wrong tool with a single dominant channel, with fewer than two years of history, with channels correlated above 0.95, or for a brand-new product. In each of those cases, experiments come first and the model later.
See it in the product